Independent work on smaller language models
Keep the useful parts. Spend less memory.
A language model is a large collection of learned numbers, called weights. Compressing them lets a model fit on less hardware. Some parts tolerate that change better than others. PrismaQuant measures the difference and gives each part the storage it needs.
Compression is a choice, made many times.
A uniform recipe gives every part of a model the same treatment. PrismaQuant can keep a small, sensitive part close to its original precision while compressing a larger, more forgiving part. The aim is to fit a memory budget without losing the behaviour you care about.
The first estimate helps choose what to try. The exported model still has to run correctly in its serving software, the program that turns a prompt into an answer. A promising estimate cannot stand in for that check.
How the method works · What the evidence does not establish
A published allocation
Each cell is a weight matrix, also called a Linear. Colour names its format; hatched cells were kept at source precision. The map records assignments, not a quality score.
Qwen3.6-27B PrismaAURA
loading…Read from the published checkpoint's metadata and tensor headers. Download map data.
Tessera · the weight format
Store fewer bits. Reconstruct what the GPU needs.
Tessera is Robert Tand's weight format, with its own plugin for vLLM. It stores a compact description of the weights and reconstructs the numbers needed for calculation. Storage size and calculation precision can be chosen separately.
The new GLM-5.3-Flash export is slightly smaller than the EXL3 reference when every file is counted on both sides. Quality and speed superiority are not established. The full serving comparison is in progress; the original matrix-level experiment favoured EXL3.
Read about Tessera and EXL3PrismaBuild · the job fleet
A small lab needs a reliable way to share its machines.
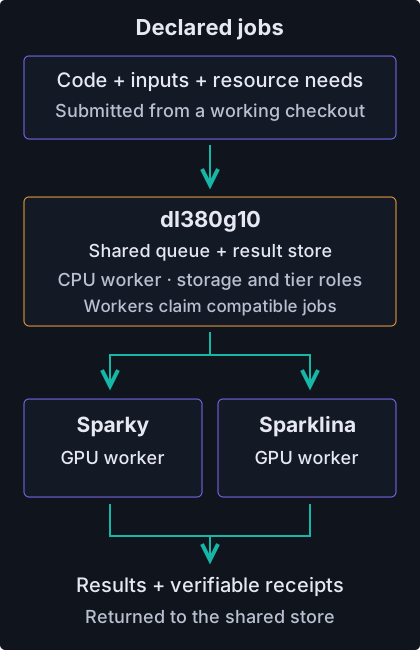
PrismaBuild is a separate build and dispatch system. It runs quantization work, tests and exports across the lab, checks whether the required resources are available, and keeps a receipt of what ran.
It also plans data movement. Fast GPUs are of little use while their inputs sit on slow disks. A staged read path brings upcoming data into faster storage before the job needs it.
Choose the download and its serving path together.
compressed-tensors
A model container that loads in vanilla vLLM, without PrismaQuant kernels.
GGUF
A model container for llama.cpp and the vLLM GGUF plugin, subject to the artifact's compatibility checks.
Tessera
The third serving lane uses Tessera's own vLLM plugin. Its exact runtime and supported combinations are pinned and checked.
A lane is a supported path from file to running model. It does not mean every model or format combination is ready to ship. Browse the published artifacts.